Reciprocal Rank Fusion: How Hybrid Search Actually Ranks
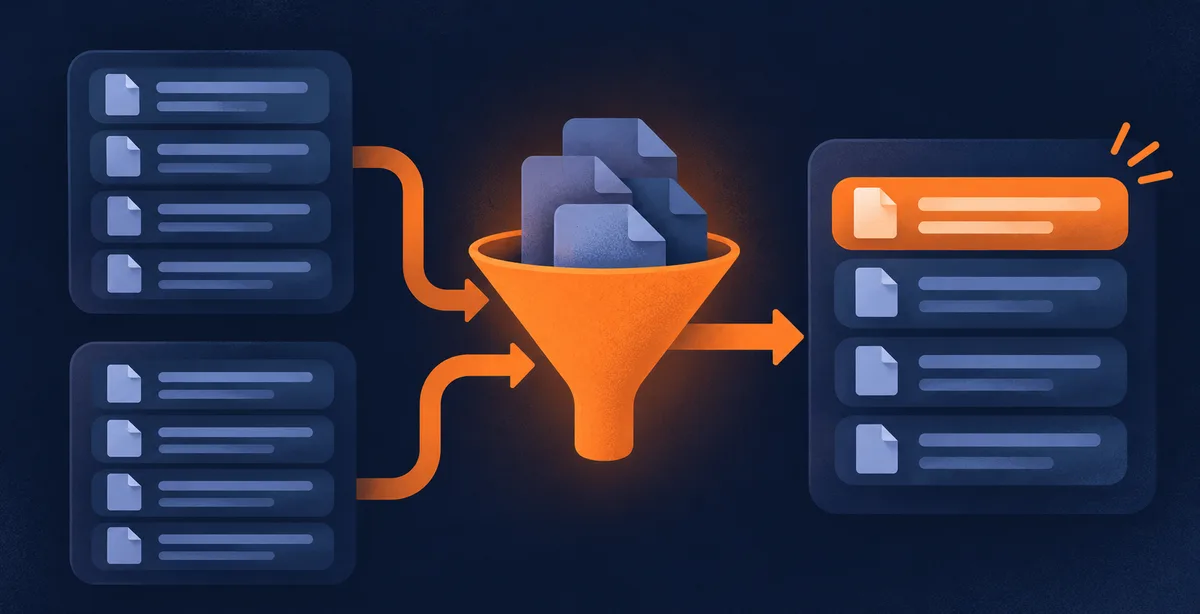
Reciprocal rank fusion (RRF) combines independently ranked search results by adding a contribution for each document’s position in each list. It uses ranks, not the retrievers’ original scores, so a lexical relevance score and a vector similarity score do not need to share a scale.
For developers, that means a straightforward interface: take an ordered list of document IDs from text search, another from vector search, and calculate one fused ranking.
The important boundary is that RRF combines existing rankings. It does not retrieve missing documents, detect query intent, recognize exact phrases, or reward freshness by itself. Those responsibilities belong elsewhere in the pipeline.
Reciprocal rank fusion explained: the formula
For a document d, standard RRF is:
RRF(d) = Σ over lists L_i containing d of 1 / (k + r_i(d))Here:
L_iis an input result list.r_i(d)is the document’s one-based rank in that list.kis a constant that controls how sharply contributions decrease with rank.- A list that does not contain the document contributes zero.
Sort documents by their fused scores, highest first.
The original 2009 RRF paper used k=60. That is a historically established starting point, not a universal optimum. Elasticsearch’s RRF documentation also describes the position-based calculation and zero contribution from lists where a document is absent.
A fused score is an aggregation value—not a calibrated probability that a document is relevant.
Why use ranks instead of adding scores?
Lexical relevance and vector similarity measure different things. Adding their raw numbers can let one retriever dominate simply because its scores have larger numerical values.
RRF avoids that problem by asking a different question: where did each retriever place this document?
If you transform the original scores while preserving every list’s membership and order, standard RRF produces exactly the same result. No shared score scale is required.
The trade-off is lost information. First place contributes the same amount whether it narrowly beats second place or leads by a huge score margin. RRF avoids incompatible raw-score scales; it does not establish that rank fusion always beats well-calibrated score fusion.
Put fusion in the right place
A FlexSearch–vector pipeline can be organized as:
FlexSearch text retrieval ──→ ranked-ID adapter ──→ candidate window ──┐
                                                                    ├─→ RRF
Vector retrieval ──────────→ ranked-ID adapter ──→ candidate window ──┘
    → optional reranking → final result limit
FlexSearch can supply the lexical side. Its basic Index interface associates text with an identifier through add(id, text) and returns matching IDs from search(query). A shared identifier lets the application join those results with vector-search candidates.
FlexSearch’s Document interface needs more care: results can be field-grouped or enriched, depending on the options. An adapter must define how those results become one ordered list. Concatenating title hits and body hits without an explicit ranking rule is not a neutral conversion.
Here, the concern is what happens after each retriever has produced an ordering.
Fusion and reranking are also different stages. Azure AI Search documents RRF merging of independently ranked hybrid results, with semantic ranking available afterward. A later reranker can use signals that the RRF formula never sees.
Worked example: merging FlexSearch and vector IDs
These are constructed lists, not measured FlexSearch or vector-engine output:
Lexical: [A, B, C, D]
Vector:  [C, B, A, E]
Use equal list weights and k=60.
| Document | Lexical rank | Lexical contribution | Vector rank | Vector contribution | Fused total, approximately |
|---|---|---|---|---|---|
| A | 1 | 1/61 | 3 | 1/63 | 0.032266458 |
| B | 2 | 1/62 | 2 | 1/62 | 0.032258065 |
| C | 3 | 1/63 | 1 | 1/61 | 0.032266458 |
| D | 4 | 1/64 | — | 0 | 0.015625000 |
| E | — | 0 | 4 | 1/64 | 0.015625000 |
Every total follows directly:
A = 1/61 + 1/63 ≈ 0.032266458
B = 1/62 + 1/62 ≈ 0.032258065
C = 1/63 + 1/61 ≈ 0.032266458
D = 1/64 + 0    = 0.015625000
E = 0 + 1/64    = 0.015625000
A and C tie exactly, because their contributions are the same two terms in opposite order. D and E also tie exactly.
For this example, resolve ties by canonical ID ascending. The result is:
[A, C, B, D, E]That tie-break is an application policy, not part of RRF. Sort using full precision, not the rounded values displayed in the table.
Why does second place in both lists lose?
B looks consistently strong, but A and C each combine first and third place. Their advantage over B is small but positive:
(1/61 + 1/63) − 2/62 = 2 / (61 · 62 · 63) > 0The contribution gained by moving from second to first is slightly larger than the contribution lost by moving from second to third.
RRF rewards cross-list appearances, but it does not simply count appearances or average rank positions.
The RRF constant is not retrieval depth
Increasing k makes contributions from different positions more similar. For positions a<b, the higher-ranked contribution divided by the lower-ranked contribution is:
(1 / (k + a)) / (1 / (k + b)) = (k + b) / (k + a)As k grows, that ratio approaches 1. Smaller values give top positions a stronger relative advantage.
Keep four controls separate:
- RRF constant: changes the contribution curve.
- Vector top-k: requests a number of nearest neighbors.
- Fusion candidate window: limits how many results from each list enter fusion.
- Final result count: limits how many ranked results the application returns.
Elasticsearch’s RRF documentation distinguishes rank_constant from rank_window_size. Azure’s documentation likewise distinguishes the RRF constant from vector nearest-neighbor k. Exact configuration interfaces depend on the engine and release.
Cut the candidate window, keep k fixed
Now truncate both constructed lists to two results:
Lexical: [A, B]
Vector:  [C, B]
Keep k=60, equal weights, and the same tie-break.
- A receives
1/61 ≈ 0.016393443. - B receives
2/62 ≈ 0.032258065. - C receives
1/61 ≈ 0.016393443.
The order becomes:
[B, A, C]B now wins without any change to the RRF constant. A and C each lost their third-place contribution from the other list. D and E disappeared from the candidate union entirely.
This is why retrieval depth belongs in ranking investigations. Zero contribution means “absent from the supplied list,” not necessarily “irrelevant.” Fusion cannot recover a document that neither retriever supplied.
Where intent, title matches, phrases, and recency belong
Standard RRF sees list membership and rank positions. Additional signals need an explicit entry point.
The following variations are independent: each starts from the original full lists and changes only the stated policy.
Query intent can choose list weights
An application can extend RRF with query-dependent weights:
WeightedRRF(d, q) = Σ over lists L_i containing d of w_i(q) / (k + r_i(d))A separate intent policy chooses w_i(q). For example, an application might favor lexical evidence for identifier-like queries and vector evidence for conceptual questions. RRF itself does not make that classification.
For the constructed lists:
- Lexical/vector weights (2, 1) produce A, B, C, D, E.
- Lexical/vector weights (1, 2) produce C, B, A, E, D.
The weights reverse which retriever’s favorite wins. These are arithmetic illustrations, not recommended tuning values.
Title preferences can change an input ordering
Suppose an application’s title preference moves B to the top of the lexical list:
Lexical: [B, A, C, D]
Vector:  [C, B, A, E]
With equal weights and k=60, fusion produces:
[B, C, A, D, E]B now combines lexical rank 1 with vector rank 2 and becomes the winner.
This demonstrates a change to the input ordering, not a particular native FlexSearch boost interface. A raw-score boost that leaves both membership and ordering unchanged has no effect on standard RRF.
An exact-phrase preference need not determine the winner
Instead, suppose a phrase preference promotes D to the first lexical position:
Lexical: [D, A, B, C]
Vector:  [C, B, A, E]
The fused order becomes:
[C, A, B, D, E]A and B tie and use the example’s ID tie-break. D improves its lexical contribution, but still receives nothing from the vector list.
If exact-phrase matches must always outrank other results, that requirement is stronger than a lexical promotion. It needs an explicit ranking policy capable of enforcing that priority.
Recency can break ties—or rerank results
Return to the base example, where A and C tie exactly. If C is stipulated to be newer than A, an application can put C first using freshness as the tie-break, with canonical ID as a fallback.
That changes the tie policy, not the RRF scores.
A broader freshness preference that can move lower-scoring documents above higher-scoring ones belongs in an explicit reranking rule. Avoid treating freshness as an invisible property of RRF.
Also watch for repeated influence: a title signal used to reorder lexical results, create a separate title list, and boost the final ranking affects the outcome at three different points.
Implement an explainable fusion layer
The core algorithm is small. The surrounding data contract deserves just as much attention.
- Choose the fusion entity. Decide whether each result represents a document, page, or chunk. If vector search returns chunks and lexical search returns documents, define the chunk-to-document aggregation before combining their ranks.
- Canonicalize IDs. Both retrievers must use identifiers that refer to the same entities.
- Establish one occurrence per entity per list. Collapse repeated field hits or chunks according to the adapter’s policy before assigning fusion ranks.
- Apply the intended candidate windows. Do not prematurely cut every input to the final display count.
- Accumulate unrounded contributions. Missing documents contribute zero; an empty list contributes nothing.
- Sort by fused score and a declared tie policy. Round only for display.
- Apply optional reranking, then the final result limit.
For diagnosis, record each candidate’s per-list rank, contribution, list weight, fused total, and any later ranking adjustment. Preserve the candidate-window settings with the query trace.
Then “Why did this result move?” has a concrete answer: its retrieval position changed, a contribution disappeared at a cutoff, its list weight changed, or a later policy reordered it.
Evaluate coverage separately from ordering
Evaluate RRF on queries with relevance judgments, rather than assuming that a plausible-looking blend is better.
Compare:
- Each retriever alone.
- Equal-weight RRF.
- Weighted RRF.
- Calibrated score fusion.
- Fusion followed by a separate reranker.
First inspect candidate coverage: did retrieval supply the relevant documents at all? Then inspect ordering quality: did the ranking place those documents near the top? A reranker cannot fix missing candidates, while deeper retrieval can change both coverage and RRF contributions.
Inspect query-intent slices separately—identifier lookups, exact phrases, and conceptual questions can expose different failures. Record latency and resource costs alongside relevance. In a local search product such as TraceMind, whose core indexing and search run on-device, the device’s resource budget matters too.
RRF’s practical value is an inspectable way to combine ordering evidence without pretending that unrelated scores are comparable. Keep retrieval, fusion, and later policy separate, and every ranking change becomes easier to explain.